Chapter: Artificial Intelligence
Learning Decision Trees
DECISION TREES
LEARNING
DECISION TREES:
•
Come up with a set of attributes to describe the
object or situation.
•
Collect a complete set of examples (training set) from
which the decision tree can derive a hypothesis to define (answer) the goal
predicate.
Decision
Tree Example:
Problem:
decide whether to wait for a table at a restaurant, based on the following
attributes:
1. Alternate:
is there an alternative restaurant nearby?
2. Bar: is
there a comfortable bar area to wait in?
3. Fri/Sat:
is today Friday or Saturday?
4. Hungry:
are we hungry?
5. Patrons:
number of people in the restaurant (None, Some, Full)
6. Price:
price range ($, $$, $$$)
7. Raining:
is it raining outside?
8. Reservation:
have we made a reservation?
9. Type:
kind of restaurant (French, Italian, Thai, Burger)
WaitEstimate:
estimated waiting time (0-10, 10-30, 30-60, >60)
Logical
Representation of a Path
r
[Patrons(r, full) Wait_Estimate(r,10 -30 ) Hungry (r,yes)} Will_wait(r)
Expressiveness
of Decision Trees
•
Any Boolean function can be written as a decision
tree
•
E.g., for Boolean functions, truth table row → path
to leaf:
•
Trivially, there is a consistent decision tree for
any training set with one path to leaf for
each
example
(unless f nondeterministic in x) but it probably won't generalize to new
examples
• Prefer to find more compact decision
trees
Limitations
–Can only
describe one object at a time.
–Some
functions require an exponentially large decision tree.
•
E.g. Parity function, majority function
•
Decision trees are good for some kinds of
functions, and bad for others.
•
There is no one efficient representation for all
kinds of functions.
Principle
Behind the Decision-Tree-Learning Algorithm
•
Uses a general principle of inductive learning
often called Ockham’s razor:
“The most
likely hypothesis is the simplest one that is consistent with all
observations.”
•
Decision trees can express any function of the
input attributes. Decision tree learning Algorithm:
•
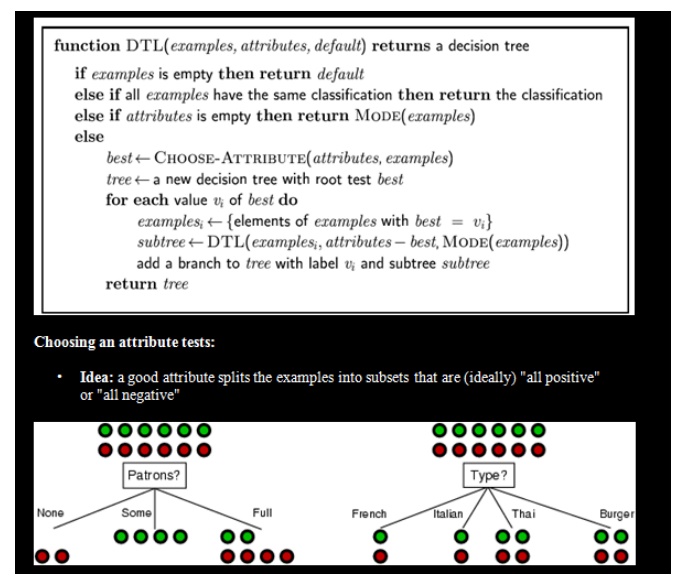
Aim: find a small tree consistent with the training
examples
•
Idea: (recursively) choose "most
significant" attribute as root of (sub)tree Choosing an attribute tests:
•
Idea: a good attribute splits the examples into
subsets that are (ideally) "all positive" or "all negative"
•
Patrons? is a better choice
Attribute-based
representations
•
Examples described by attribute values (Boolean,
discrete, continuous)
•
E.g., situations where I will/won't wait for a
table:
•
Classification of examples is positive (T) or
negative (F) Using information theory
•
To implement Choose-Attribute in the DTL algorithm
•
Information Content (Entropy):
I(P(v1),
… , P(vn)) = Σi=1 -P(vi) log2 P(vi)
•
For a training set containing p positive examples
and n negative examples:
A chosen
attribute A divides the training set E into subsets E1, … , Ev according to
their values for A, where A has v distinct values. Information Gain (IG) or
reduction in entropy from the attribute test: remainder ( A),
·
Choose the attribute with the largest IG
•
For the training set, p = n = 6, I(6/12, 6/12) = 1
bit
•
Patrons has the highest IG of all attributes and so
is chosen by the DTL algorithm as the
root
Assessing
the performance of the learning algorithm:
•
A learning algorithm is good if it produces
hypotheses that do a good job of predicating the
classifications
of unseen examples
Test the
algorithm’s prediction performance on a set of new examples, called a test set.
Patrons
has the highest IG of all attributes and so is chosen by the DTL algorithm as
the root
·
Choose the attribute with the largest IG
•
For the training set, p = n = 6, I(6/12, 6/12) = 1
bit
·
Assessing the performance of the learning
algorithm:
•
A learning algorithm is good if it produces
hypotheses that do a good job of predicating the classifications of unseen
examples
Related Topics